GPT 3
Background
A transformer model is a recurrent neural network which can process sequential data parallel. It means it can process a sentence in any order. It was observed that transformer models which are trained on very large data sets tend to learn quite better. It was in 2018 that the researchers of OpenAI came up with The Generative Pre-trained Transformer series which was a deep learning model trained on very large data sets. In November 2019, GPT 2 was released for common public which was considered a state of the art model due to its high accuracy. NVIDIA, soon released Megatron, which was followed by Microsofts Turing NLG. Below is comparison table showing the number of ML parameters or the amount of data on which these models were trained.
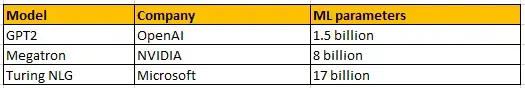
GPT3 was considered a “Game Changer” in this series as it was trained on 175 billion ML parameters, which is 10 times of Turing NLG and more than a 100 times of its predecessor GPT2. It was trained with V100 GPU’s on the part of high bandwidth clusters.
Measuring Performance
A language model performance is rated in terms of how accurately it responds on a particular topic with or without any data fed to it about the topic.
Few shot learning : In addition to the task it has to perform, it is given a few examples of the task along with the answer.
Lets take a simple task of language translation. Translate “¿Cómo está usted señor?” to English. In Few shot learning method or scenario, the model is given a few examples of similar translation, so it knows what the task is all about.
Task : Translate Spanish to English
Examples:
Buenos Dias! — Have a Good Day
¿Como te llamas?- What is your name?
¿Cómo está usted señor? — ?
So, here the model knows what the task is, and how similar tasks were correctly responded. Using this information, it tries to best guess what would be the most appropriate next word, which would be the translated sentence for ¿Cómo está usted señor?.
For simplicity, you can even consider it as a basic fuzzy search this model does into the vast database of 175 billion parameters. First it searches for the task “Translate Spanish to English”. Then it has a few examples which helps it to narrow down its search.
The other types of methods or scenarios include –
Zero shot model — where only the task is given without any examples for the model to respond.
One shot model — where a task and one example is given to the model to respond.
As you can see, the accuracy of the previous models (GPT2, Turing NLG) which were trained on 1.3 billion and 13 billion ML parameters respectively showed minimal improvement for different types of scenarios (few-shot, zero shot, one shot). With GPT 3 where the training data was 175 billion parameters, they were able to achieve an accuracy of nearly 65 percent with few-shot learning method.

What can it do?
Apart from translating text is different languages, answering questions, predicting or generating texts, its applications can be found for literally anything which could assist a professional in any field.
- Tired of writing long mails. Generate mail body from just the subject
Here is a link to join their beta version —
https://magicemail.io/waitlist?&ref_id=O7PKG
2. Assist programmers in writing code
3. Well, if you are running short of business ideas. It can generate some for you too. https://ideasai.net/
The above ones are a few among them. The applicability of the model is huge and with many researchers using it, each day it does surprises us with something which seemed extra-ordinary a few years back.
Controversies and Drawbacks
Over-hyped
Many researchers in the field claim that this model is just an extended version of GPT 2 and nothing new or innovative. The only difference is that it is trained on data 100 times of that of GPT2.
Performance parameters
While the performance of the model is very high for certain parameters. It was also observed that the accuracy of the model remained fairly constant for some cases even though it was fed with this huge quantity of test data.
Misuse
The ease it brings to the table has often raised concerns over the misuse of this model. A few cases reported recently included a school student generating content automatically for his website as well as for his homework. Many other misuse cases include email spamming etc are identified.
Final Thoughts
GPT3 has created the hype of language models and while it is true that its not different from its predecessor, the amount of accuracy it brings to the table has literally sky-rocketed its popularity as well as applicability. Yes, the model is not different, but to find out about its high accuracy when trained on a very large DB set was a great finding.
While its still made available to a very few people by OpenAI on the context of possible misuse, I believe highly trained models will soon be a thing in the coming future and would push us to develop some highly innovative applications.
Some people might fear that the coding jobs would get redundant with high capability AI’s taking over this task. I believe its important to understand that we as humans have always evolved from our past. If coding jobs would ever get redundant, there would be some highly interesting jobs in different fields which would be assisted by these super functional AI machines to carry out some innovative tasks which are considered impossible today.
The concern over AI taking over the human race is a valid concern, considering AI’s are now given a wide set of independence in making their own inferences etc. but as many prominent people have pointed out that the need to make sure we progress ourselves along with the rapid progress in technology and be at the forefront is very important as it is only human to innovate. So, if we are not there, someone with malicious intent might invent it first.
Amongst all the controversies going around GPT3, I still believe its a huge leap inducing high hopes in the AI natural language community. Hope this is just the beginning of an interesting era.
P.S : This article is completely self written by me and no part of it is generated by any AI